Character Recognition
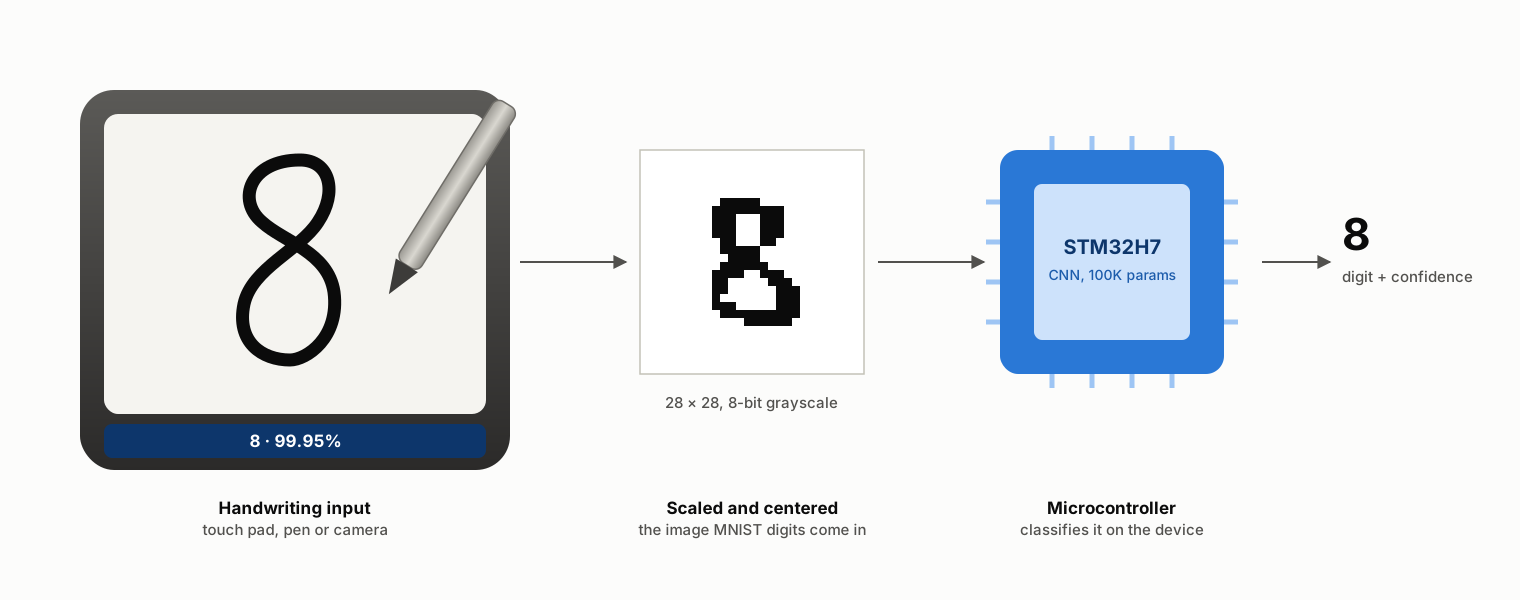
Handwriting recognition that runs entirely on a microcontroller. No cloud, no network connection. We trained two neural networks on 60,000 handwritten digits, compared them head to head on 10,000 more from different writers, and our library runs this same task live on an STM32H7.
- accuracy on MNIST's standard 10,000-digit test, from writers it never saw
- 99.41%
- parameters, small enough for a microcontroller
- 100,254
- of flash as 8-bit integers, with no loss of accuracy
- 99 KB
- the microcontroller in our live demo
- STM32H7
Where it's used
A small image in, an answer out, all on the device
Lots of products need to turn a small picture into an answer on the spot. When the network runs on the device itself, it works without a connection, it answers right away, and the data never has to leave the product.
Reading handwritten digits is a great example of that kind of model, and it’s the same approach behind products like these.
- A smart pen digitizing handwritten forms
- A point-of-sale device reading a handwritten amount
- A meter reader recognizing a dial
- A postal sorter reading a ZIP code
The data
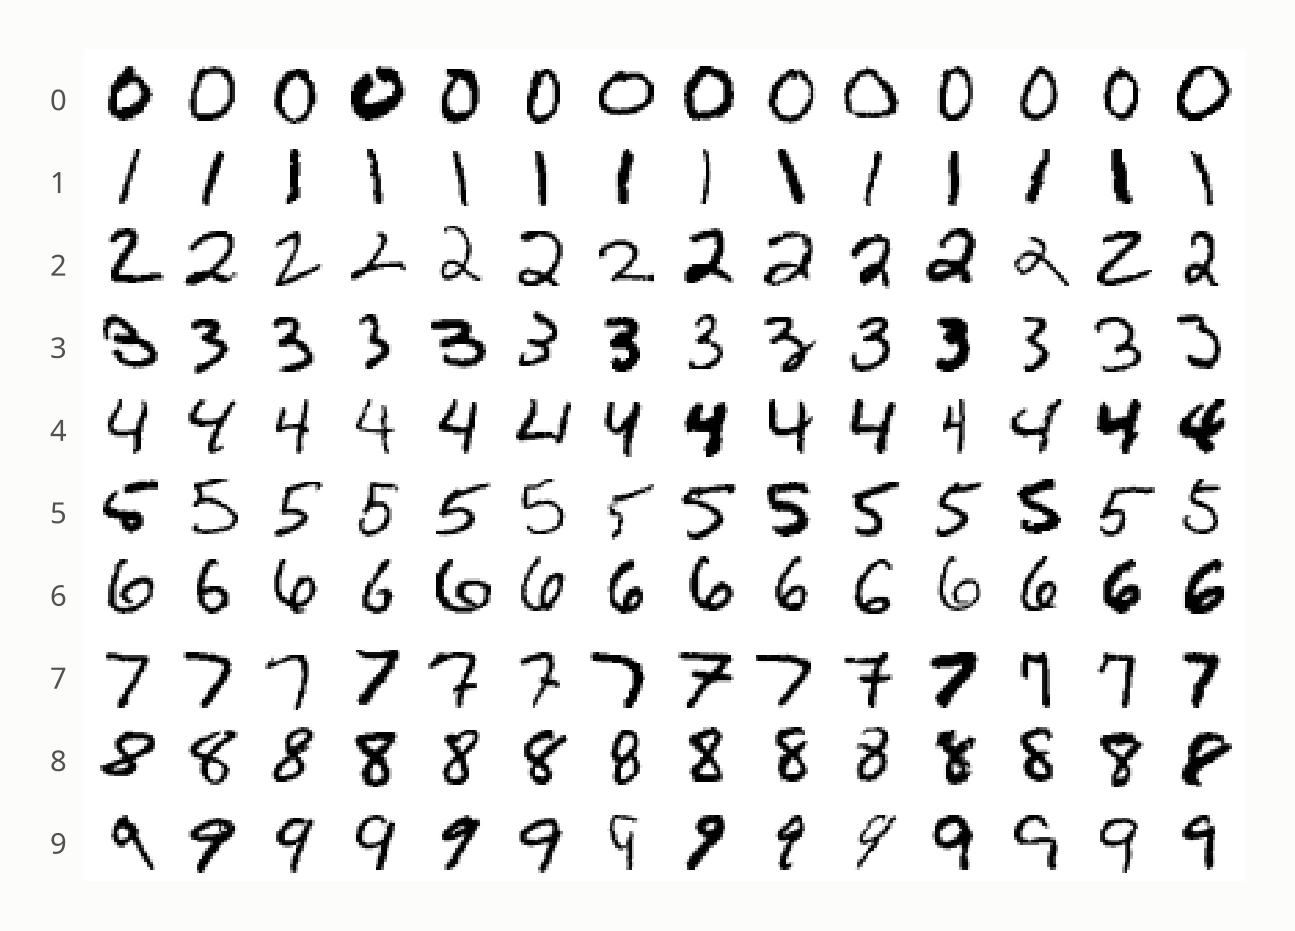
70,000 handwritten digits
We trained on MNIST, the classic handwriting benchmark: 70,000 digits, each a 28 × 28 grayscale image. We kept its standard split, so every digit we test on was written by someone the networks never learned from, and our results compare directly with published ones.
- Training · 77%, 54,000 digits
- what the networks learn from
- Validation · 9%, 6,000 digits
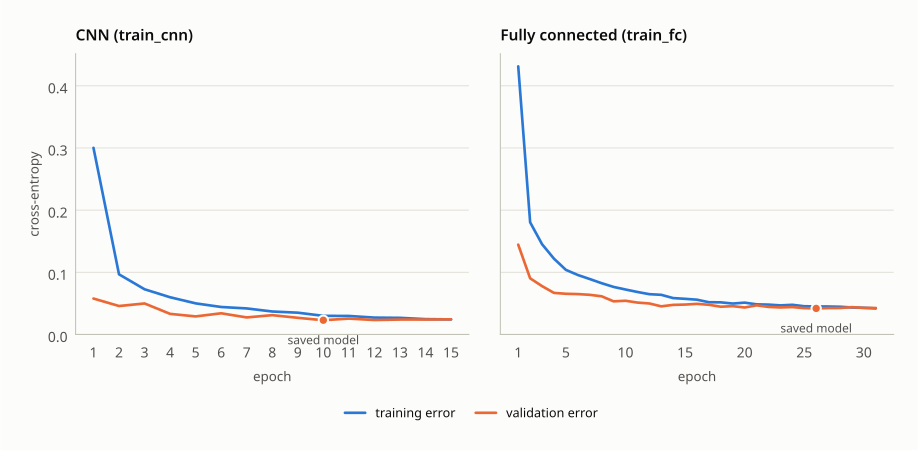
- checked after each round of training, so we keep the best model
- Test · 14%, 10,000 digits
- MNIST's own test set, written by different people, and kept aside until the very end. The 99.41% comes from these.
How we built it
Two networks, one test
Instead of training one network and reporting a number, we built two different kinds, trained them on identical data and graded them with the same test, so the comparison is a fair one.
Convolutional network train_cnn.c
This one scans the image with small 5 × 5 filters that pick out strokes, combines those into shapes, and then hands the result to a few final layers that decide which digit it is. Only 3,424 of its 100,254 parameters sit in the filter layers, but that’s where most of the arithmetic happens, about 880,000 multiply-adds per digit in total.

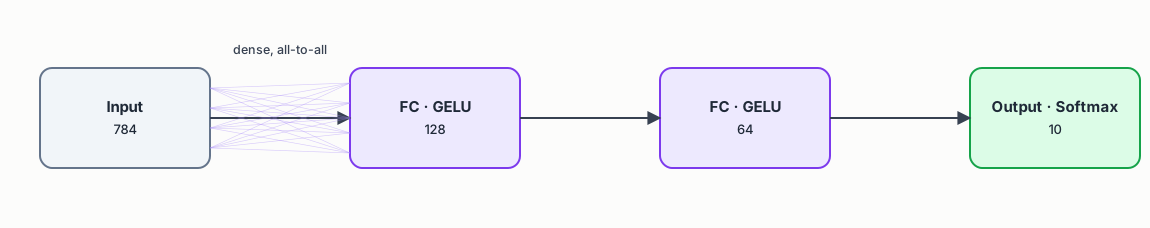
Fully-connected network train_fc.c
The classic alternative wires every one of the 784 pixels straight into a layer of 128 units, then 64, then the answer. It’s a similar size at 109,386 parameters and needs only about 109,000 multiply-adds per digit, but it has no sense of which pixels sit next to each other. It’s the network a convolutional design has to beat to earn its place.
Trained to expect the unexpected. Real handwriting never sits exactly where the dataset’s does. Every round of training, each digit is moved a pixel or two at random, so the networks learn that position doesn’t matter.
Results
Half the mistakes, the same number of weights
| Network | Parameters | Multiply-adds per digit | Epochs | Training time per epoch | Train accuracy | Test accuracy |
|---|---|---|---|---|---|---|
| Convolutional train_cnn | 100,254 | ~880K | 15 | 48 s | 99.70% | 99.41% |
| Fully connected train_fc | 109,386 | ~109K | 31 | 1.3 s | 99.09% | 98.71% |
Training times are on a single desktop CPU core. The convolutional network’s accuracy is our reference model; across six training runs it scored 99.29–99.42%, and its epochs and time per epoch come from the median run. The fully-connected row is the median of five runs, which scored 98.66–98.81%.
Why it wins
With slightly fewer parameters, the convolutional network makes about half the mistakes on digits from writers it’s never seen: 59 out of 10,000, against 129. That also beats LeNet-5, the network this benchmark was introduced with, at 99.05%. Convolutional filters look for strokes wherever they appear, so what the network learns carries over to handwriting it hasn’t met before.
What it takes
The extra accuracy comes from arithmetic, not more weights. Each digit takes about eight times the multiply-adds, and training takes about 38 times as long. On a device reading one digit at a time, it still works out to just milliseconds.
Mistakes a person could make
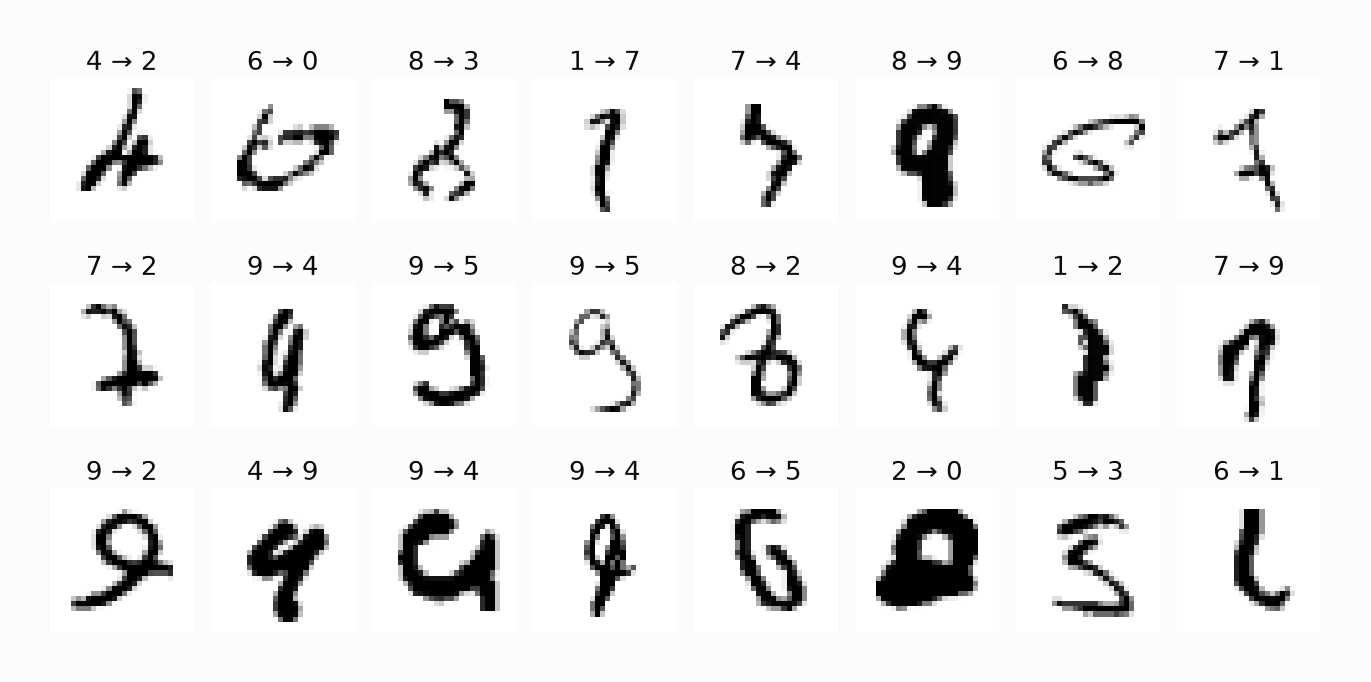
Many of the digits it gets wrong are hard to read for anyone. Think 9s with an open or squashed loop that pass for 4s or 5s, and 7s written with a crossbar that look like 2s.
On the device
Small enough for a microcontroller
Converted to 8-bit integers, the trained network takes 99 KB of flash and scores exactly as well as it did before. It runs straight out of flash, with about 32 KB of RAM for its working buffers. An STM32H743 has 2 MB of flash and 1 MB of RAM, so there’s plenty of room left for the rest of the product’s firmware.
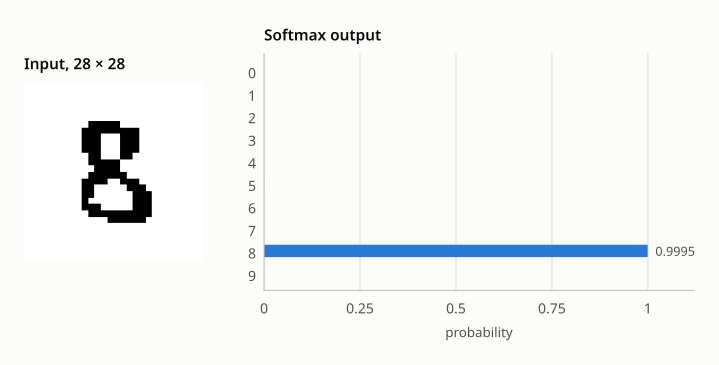
The code on the device is short. It takes the image from the touch panel or camera, scales it to 28 × 28, hands it to the network and reads off the answer. At about 880,000 multiply-adds per digit, that works out to a few milliseconds on a Cortex-M7 running at several hundred megahertz.
Want this in your product?
We build embedded AI like this into medical and industrial devices, from the sensors and firmware to the network running on the chip. Tell us what yours needs to recognize.
Founded in 2008 · Hudson, Ohio · info@coledd.com